If you are designing fine-grained authorization, someone on your team has probably said "do it like Google Zanzibar". It usually comes up when the product has sharing, teams, folders or account managers, any rule where access depends on how a person is connected to a record. Zanzibar is the system Google described in a 2019 paper for managing permissions across Drive, YouTube, Calendar and its other products, and it made relationship-based access control (ReBAC) the model many teams reach for first.
Policy-based access control (PBAC) handles the same rules from a different starting point. The question for your application is not which model is more advanced, but where the facts behind each decision live, who keeps them current, and what you can show when someone asks why a person was allowed in. This guide compares the two models on those three questions, with a worked policy for a real rule.
What policy-based access control (PBAC) is
In policy-based access control, every decision comes from a policy evaluated against the request. The request says who is asking, what they want to do and to which resource, with the attributes that matter, such as the person's department, the record's owner, its status or its region. The policy says which combinations are allowed.
PBAC is a way of organizing authorization rather than one rule type, so it contains the others. Role-based access control is a policy that checks roles. Attribute-based access control is a policy that checks attributes. Relationship-based access control is a policy that checks how the person is connected to the resource, such as "owns it", "is on the team that owns it" or "is the assigned adviser for this client". In Cerbos, the authorization management platform this guide uses for its examples, policies are YAML files with conditions in CEL, Google's Common Expression Language, so a security reviewer can read a rule in a pull request.
What Google Zanzibar is, and what the paper describes
Zanzibar is Google's internal authorization service, described by Ruoming Pang and colleagues at USENIX ATC 2019. Google never released it as a product. What exists outside Google are implementations inspired by the paper.
The model is built on relation tuples, one stored record per relationship, written as object, relation and user. "Document readme has viewer anne" is one tuple, and "group eng has member anne" is another. The user in a tuple can itself be a set, such as "members of group eng", which is how groups nest. Each type of object gets a configuration with rewrite rules that derive one relation from another, so editors are also viewers, and a document's viewers include the viewers of its parent folder. A check follows those tuples and rules until it reaches the person or runs out of paths.
Three more pieces matter in practice. Zookies are consistency tokens that let a client ask for a check at least as fresh as a given change, which stops a stale check from showing a person something they lost access to moments earlier. A Watch API streams tuple changes to other systems. Leopard is a separate index Google built for deeply nested groups, because following group membership hop by hop was too slow at Google's depth.
The scale numbers in the paper are real and often quoted. More than two trillion relation tuples, more than 10 million client queries a second, under 10 milliseconds at the 95th percentile and more than 99.999% availability over three years, on Spanner, Google's globally distributed database, across more than 30 locations. Those numbers describe Google's own deployment and its team. An implementation you run inherits the model, not that infrastructure.
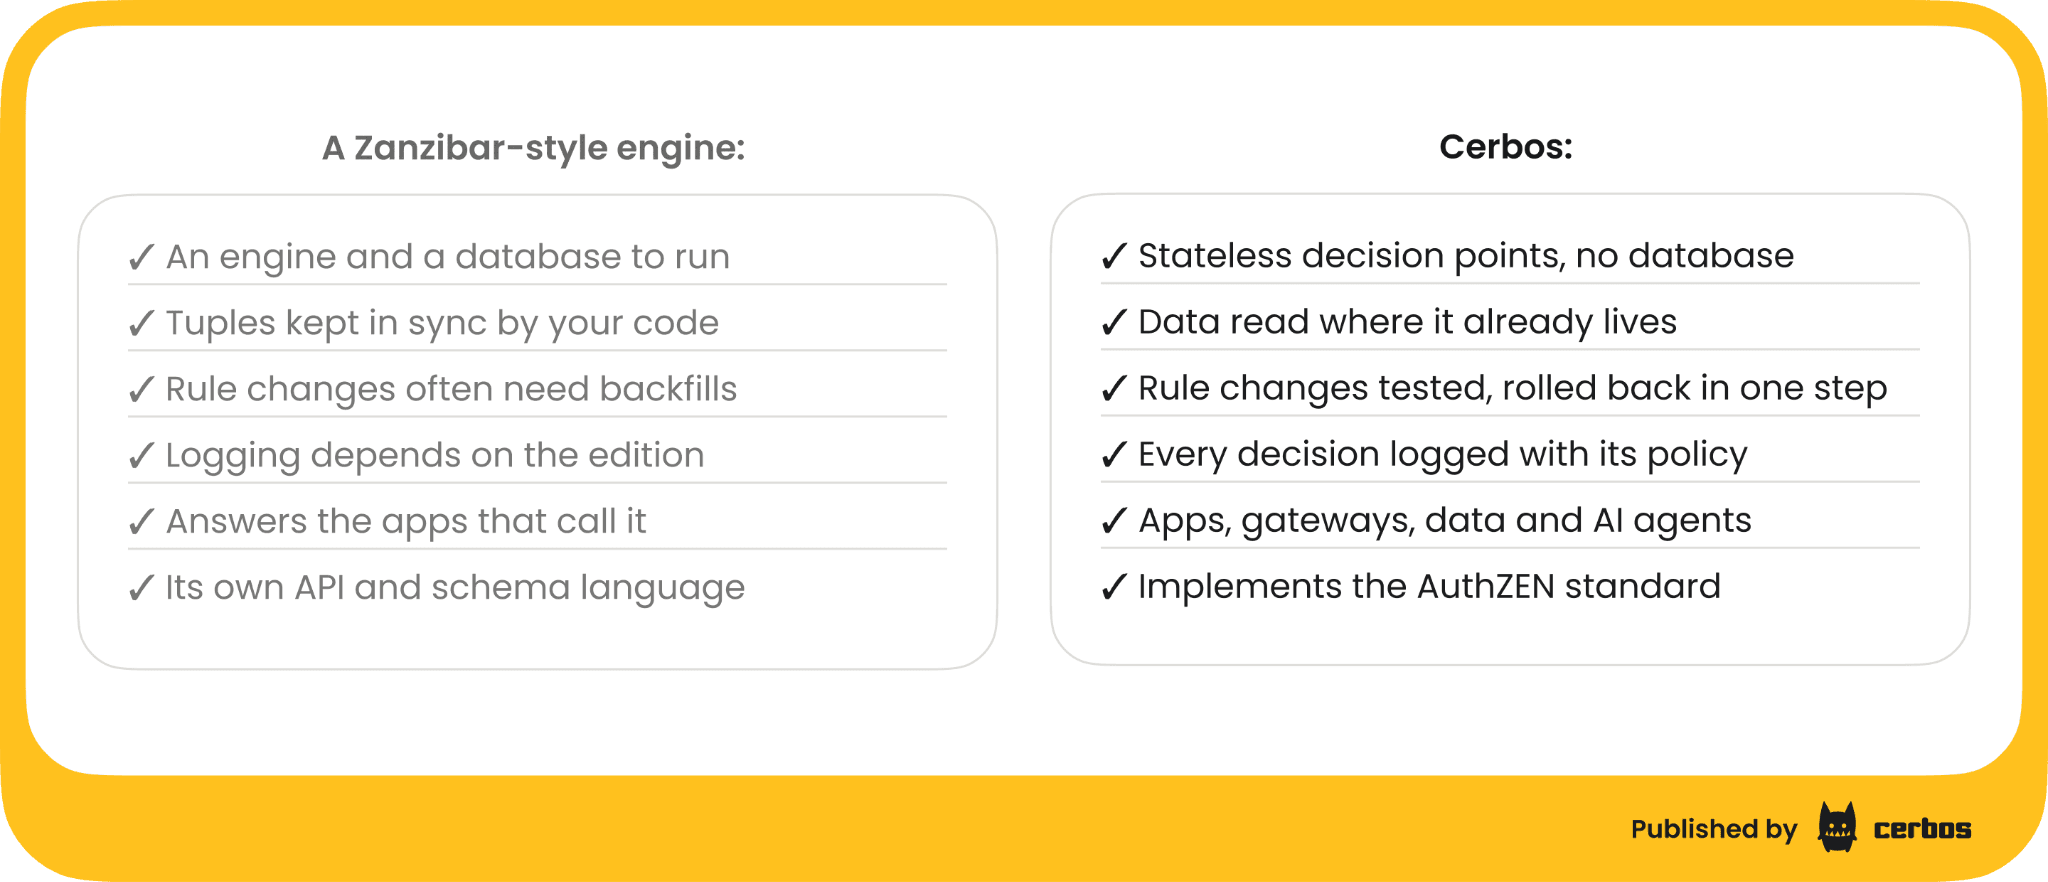
PBAC vs Zanzibar at a glance
| Question | PBAC (as in Cerbos) | Zanzibar model |
|---|---|---|
| Unit of authorization | A policy evaluated against a request | A stored relation tuple, followed through rewrite rules |
| Where the facts live | Where they already are, sent with the request or fetched at decision time | In the authorization system's own store, written there by your application |
| Attributes such as amount, region, status, time | Part of the core model, in the same rule as relationships | Added on top of relationships, as conditions or context sent with a check |
| Freshness of a decision | As fresh as the data the request carries or fetches | As fresh as the last tuple write, managed with consistency tokens |
| "What can this person see?" | A query plan your database runs as a filter | A lookup across the stored relationships |
| Explaining a decision afterwards | The decision, its inputs and the policy version that made it | The tuples that matched, if your implementation logs them |
| Changing a rule | Edit and test a policy, then roll it out. A rule that needs a new fact reads it from the system that already holds it | Edit the schema, then often rewrite or backfill tuples |
How PBAC and Zanzibar handle relationships and attributes
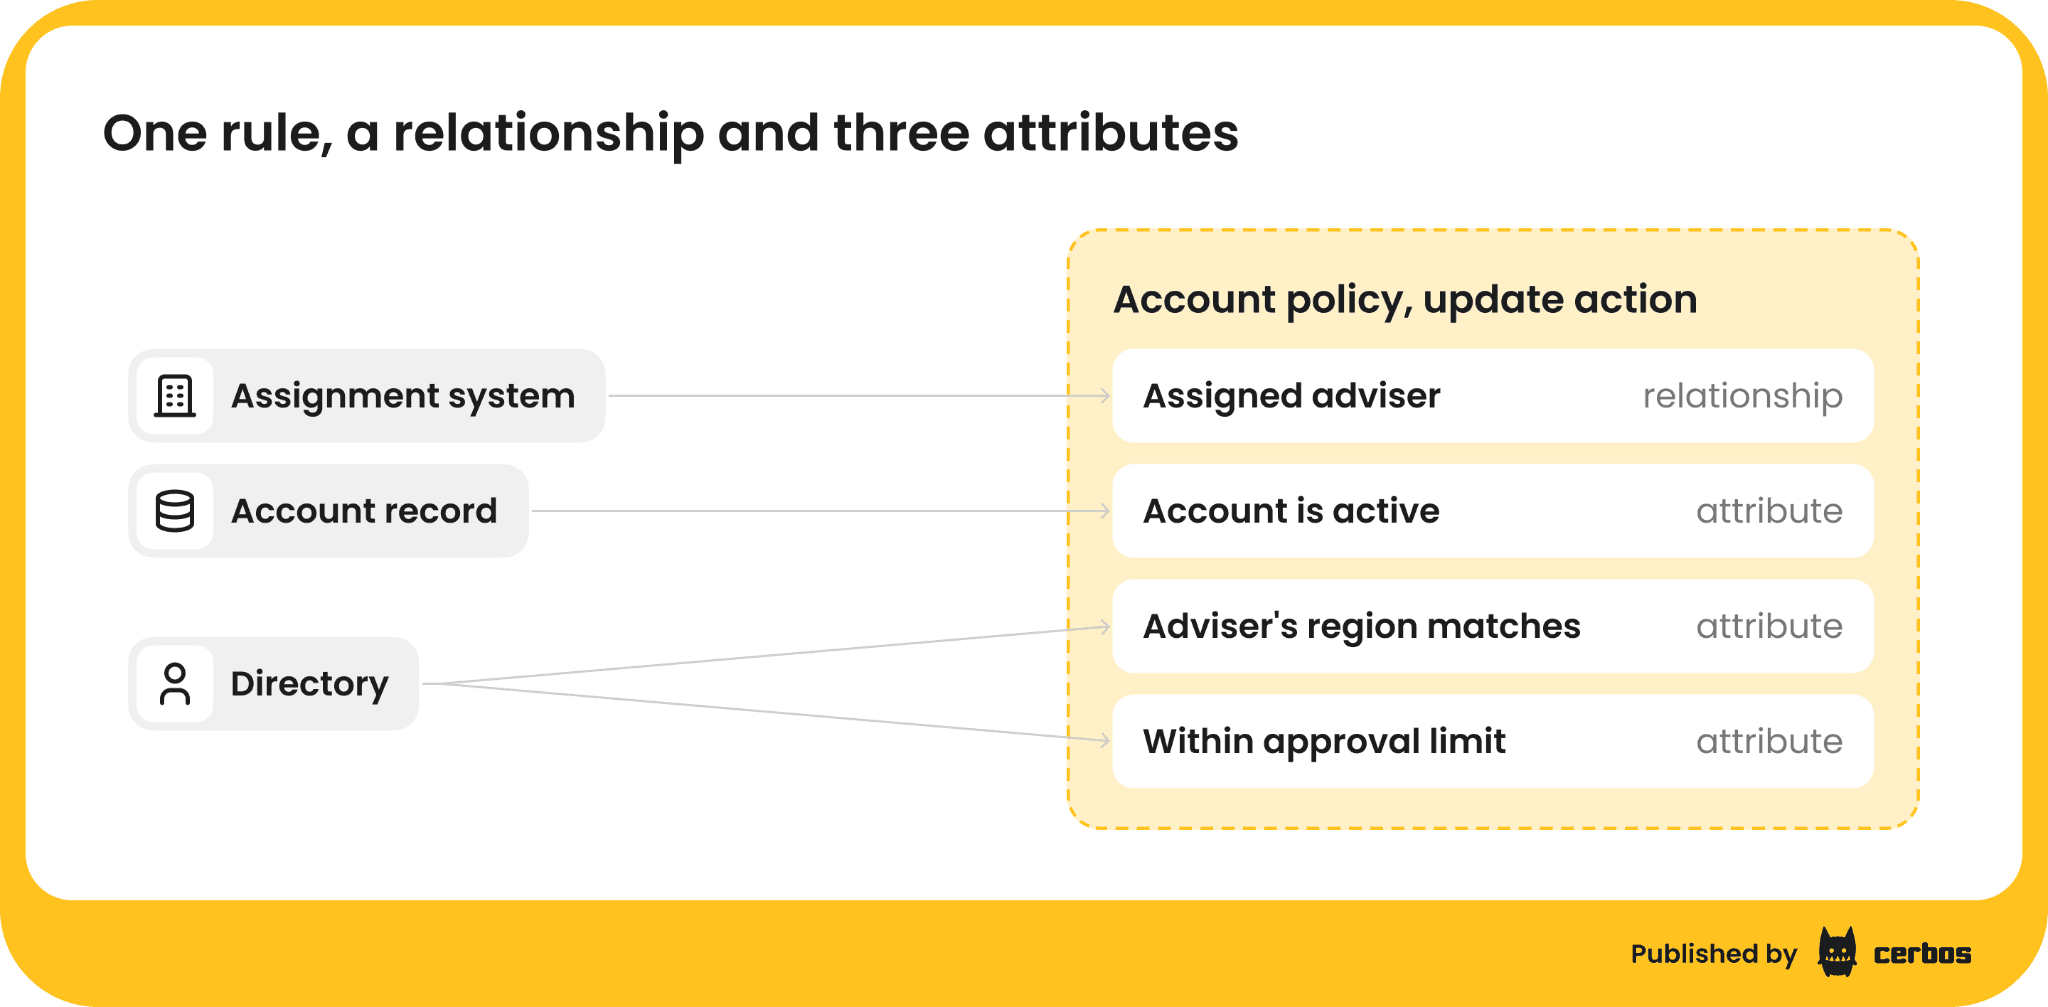
Real permission rules almost never stop at a relationship. A bank adviser can see the accounts of the clients assigned to them, but can only change an account that is active, in their own region and within their approval limit. The first half is a relationship. The second half is three attributes.
In the Zanzibar model, the relationship half is a tuple per adviser and client, kept current as assignments change. The attribute half has to arrive another way. Implementations add conditions on tuples, or contextual facts sent with each check, as a second mechanism next to the graph.
In PBAC, both halves are one policy. The relationship becomes a derived role, granted when the account's client is one of the adviser's assigned clients.
apiVersion: api.cerbos.dev/v1
derivedRoles:
 name: account_relationships
 definitions:
   - name: assigned_adviser
     parentRoles: ["adviser"]
     condition:
       match:
         expr: R.attr.clientId in P.attr.assignedClients
The resource policy then uses that relationship and adds the attribute rules in the same place.
apiVersion: api.cerbos.dev/v1
resourcePolicy:
 resource: account
 version: default
 importDerivedRoles:
   - account_relationships
 rules:
   - actions: ["view"]
     effect: EFFECT_ALLOW
     derivedRoles: ["assigned_adviser"]


   - actions: ["update"]
     effect: EFFECT_ALLOW
     derivedRoles: ["assigned_adviser"]
     condition:
       match:
         all:
           of:
             - expr: R.attr.status == "active"
             - expr: R.attr.region == P.attr.region
             - expr: R.attr.balance <= P.attr.approvalLimit
An adviser assigned to the client can view every one of that client's accounts and update only the ones that pass all three checks. An adviser for another client gets nothing. The policy compiles with Cerbos 0.57.0. Organization and tenant trees use the hierarchy functions in CEL, and our post on hierarchy-based permissions covers more patterns.
Where the data lives in PBAC and Zanzibar, and the dual write problem
Every fact a decision depends on has to be somewhere the decision point can read it, and this is where the two models part most.
In the Zanzibar model, the authorization system keeps its own copy of every relationship. When an adviser is assigned in your CRM, a client moves to another team or a document is shared, your application writes the change to its own database and writes a tuple to the authorization store. No transaction spans the two, so a crash, a retry or a failed write between them leaves them disagreeing, and a delete in your database does not cascade on its own. This is known as the dual write problem, and the vendors who build Zanzibar-style engines describe it as hard to solve and publish lists of workarounds, from a transactional outbox to event sourcing and durable execution. One engineering team rewrote OpenFGA in Postgres so that permissions read their existing tables, after finding the big problem was "keeping everything in sync all the time".
For an identity team, a tuple that drifted from the source is access nobody meant to grant, or a leaver whose access never ended. For an engineering team, every new feature that touches permissions adds another write path to keep correct, and every schema migration has a second store to migrate with it.
In PBAC as Cerbos does it, the decision point keeps no copy. Cerbos PDP, the policy decision point, loads policies and no data, so it has nothing to drift out of step with your systems. The application sends the attributes it has already loaded, and Cerbos Synapse fetches the rest at decision time from the system that owns them, a SQL database through its built-in data source, an identity provider such as Okta or Entra ID, or any other store, a graph database included, through a custom data source. Cache times are set per source, so a team decides how fresh each fact must be. We cover the pattern in our post on reading attributes from the database. A change in the source applies on the next request that reads it, or once the cache time you set for it runs out, because there is nothing to sync.
Both models have to bring the data to the decision. A Zanzibar system does it on every write, by keeping a second store current with every change in your systems. In Cerbos, most applications already have the record in hand when they ask the question, so Cerbos Synapse only fetches what they do not, with a cache time you set per source.
Consistency in PBAC and Zanzibar, and the new enemy problem
The Zanzibar paper names a failure it calls the new enemy problem. Remove Bob from a folder, then add a new secret document to it, and a system that applies the two changes out of order, or checks against a stale replica, can show Bob the new document. Zanzibar prevents this with zookies, so a check can demand data at least as fresh as the change that matters. Implementations carry the same idea as consistency tokens, and the application has to store and pass them correctly.
The problem comes from evaluating against a copy that lags behind the source. When a policy is evaluated against attributes read from the source of truth on the request, there is no second copy to lag, and freshness is whatever the source and your cache settings give you. For revocation-sensitive facts, such as group membership or an account freeze, set a short cache time or none at all, and a change in the source reaches the next request.
PBAC query plans vs Zanzibar lookups for listing what a user can see
A search page, a dashboard or a retrieval step for an AI assistant asks a different question from a check. It needs everything this person can see.
A Zanzibar-style engine follows the stored relationships and returns object IDs, which your application then loads from its own database, and then sorts and pages on its own. Some implementations limit a lookup. OpenFGA’s documentation, read in October 2026, sets a default limit on how many results its list endpoint returns and how long it runs.
In Cerbos, a query plan turns the policy into a filter that your database runs, so the database returns the rows the person may see, sorted and paginated as usual, with no separate result cap.
Explaining a decision afterwards in PBAC and Zanzibar
Months after an access, a regulator or an incident review needs the rule that allowed it, not only the data that existed at the time.
The Zanzibar paper describes a consistent, fast check, not an audit trail, and what a Zanzibar-style engine records depends on the implementation and on the logging you build around it. What you can usually reconstruct is which tuples existed at the time, not which rule allowed the request.
Cerbos logs every decision with its inputs, its outcome and the policy version behind it. Cerbos Hub, the part of the platform that manages policy and audit, collects those logs from every decision point into one searchable trail, which you can export to your own archive or SIEM, and the Git history of the policy sits next to it. For a security team, "show me the policy that was in effect at the time" becomes a search rather than a reconstruction.
PBAC and Zanzibar for AI agents
An AI agent acting for a person raises three questions in one request. Is this agent allowed to call this tool, is the person behind it allowed to touch this data, and does the action fit the limits set for agents today? A relationship graph can say the person is connected to the record. The agent becomes one more subject, and the tool's arguments and a value threshold have to travel as extra context on every check, next to the graph rather than in the rule.
A policy answers all three questions in one rule. Cerbos checks each agent tool call before it runs, down to its arguments, through a hook in the agent, an MCP gateway or the MCP server itself, with the agent's token and the person's token in the same request. Our guide to MCP authorization walks through it.
Zanzibar-style implementations in today's time
Teams that pick the Zanzibar model choose an implementation, since Google's own is not available. As of October 2026, OpenFGA is a CNCF Incubating project, accepted in late 2025, and Okta sells a managed version as Auth0 FGA. AuthZed develops SpiceDB and sells it as a hosted and dedicated service. Ory Keto describes itself as the first open source implementation of the paper. Permify became part of FusionAuth in November 2025, and Aserto shut down its hosted service at the end of May 2025. Each has its own schema language, consistency options and limits, so the paper tells you the model and not how a given product behaves. Our Cerbos vs OpenFGA comparison covers OpenFGA in detail.
Which fits your application, PBAC or Zanzibar
For most applications, policy-based access control is the better fit. Most permission models are one or two relationship hops, such as owner, team, tenant or assigned adviser, plus attributes such as status, region, amount and time. A policy holds all of that in one readable rule, evaluated against data where it already lives, with no second store to keep in sync and a record of every decision.
The Zanzibar model was built for a specific problem, Google’s sharing graph, where people and groups share objects ad hoc at the scale of trillions of tuples, with a dedicated team to run it. If the core of your product is that problem, a reverse lookup of who can see each object across a very large and fast changing sharing graph, test that part with your real data. Cerbos Synapse can read that graph where it lives, and everything around it, the attribute rules, the gateways, the agents and the audit trail, still belongs in policy.
As Joe Qureshi, Senior Software Engineer at 9fin, put it, "I can quickly and confidently change rules on policies. And I struggle to think of requirements that can't be expressed in the policy format Cerbos has developed."
Try Cerbos with a relationship rule from your own product. Your engineers write the relationship and the attribute checks it depends on as one tested policy, your identity team sees access follow the assignments and groups your systems already hold, and your security team reviews every rule change in a pull request before it ships.
If you are weighing the two models for a real system, book a call with our team and bring the relationship rule you are least sure how to model.
Go deeper:
- Cerbos vs Zanzibar
- Migrating from SpiceDB to Cerbos
- Building a scalable authorization system (eBook), a step-by-step blueprint for authorization architecture
FAQ
Tagged in